Every capital project funding review eventually arrives at the same slide. There's a base estimate, a curve, and two or three numbers labeled P50, P80 and maybe P90. Someone points at the P80 and says, "So we're 80% sure it comes in under that."
That sentence is close enough to sound right and far enough off to cause real trouble. Here's what those numbers actually are, what they quietly assume, and the questions worth asking before anyone leans on one.
A P-value is a percentile of simulated outcomes
A Monte Carlo cost model doesn't produce one answer. It takes the estimate, puts ranges on the uncertain parts, adds discrete risk events with their probabilities and impacts, and then draws thousands of possible project outcomes. Sort those outcomes from cheapest to most expensive and you have a distribution.
A P-value is a position in that sorted list:
- P50 is the cost that half the simulated outcomes come in at or below. It's the median of the model.
- P80 is the cost that 80% of the simulated outcomes come in at or below. One in five simulated outcomes is higher.
- P90 is the same idea further out in the tail.
That's the whole definition. It says nothing yet about the real project. It describes the model.
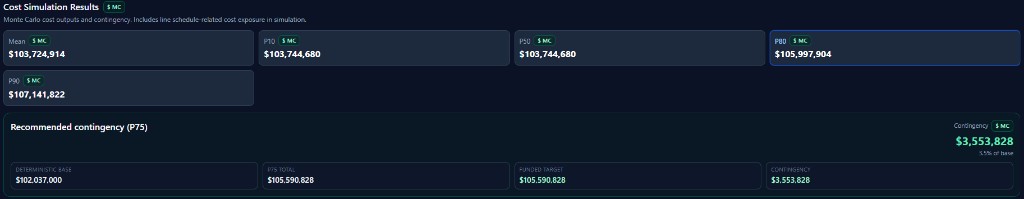
"80% confident" is really "80% under this model"
The honest reading of a P80 is conditional: if the ranges, events, correlations and exclusions in this model are a fair description of the project, then 80% of outcomes fall at or below this number.
Every word in that "if" matters.
- The ranges. A line with a low-to-high range drawn from a single optimistic conversation produces a narrow curve. The P80 inherits that optimism.
- The risk events. A register that leaves out the risk everyone privately worries about can't price it. The model can't see what nobody entered.
- The exclusions. Scope that's explicitly excluded from the estimate is excluded from the distribution too. A P80 on a partial scope is a P80 on a partial scope.
- The estimate version. The simulation is tied to a specific estimate basis. If the estimate changed after the run, the P80 on the slide describes a project that no longer exists.
None of this makes the number useless. It makes it a statement about a model, and the model is something a reviewer can open up and question.
What P80 is not
A few readings are worth ruling out directly, because they show up in almost every review:
It's not the most likely cost. The most likely single outcome, the peak of the distribution, usually sits below the P50 on a cost curve, because cost risk tends to be skewed toward overruns. The P80 is further out still.
It's not a guarantee. One in five modeled outcomes is higher. On a portfolio of projects all funded at P80, you'd expect some to need more.
It's not the contingency. Contingency at a given confidence level is the gap between that P-value and the base estimate. It's a derived number, and it moves when either side moves.
It's not a funding decision. Which confidence level to fund is a judgment about risk appetite, the owner's portfolio, contract structure and what happens if the money runs short. A P50 might be reasonable on one project and reckless on the next. The analysis tells people what each level costs. People decide which level to fund.
Correlation is where most curves go wrong
A frequent technical flaw in a cost risk model isn't a bad range. It's treating every line as independent.
When each line's uncertainty is drawn independently, highs in one place cancel lows in another. With enough lines, the cancellation is dramatic: the distribution narrows, the P80 slides toward the P50, and the contingency at P80 looks small and reassuring.
Real projects don't behave that way. When the market for skilled trades tightens, it affects most of the labor on the job at once. When design development grows piping quantities, it often grows supports, insulation and testing with it. Those costs move together, and a model that ignores that relationship will understate the spread.
You don't need a perfect correlation matrix. You need one that reflects the relationships your estimators already know exist, and diagnostics that tell you when it's incomplete.
Double counting pushes the other way
The opposite error is quieter. If escalation is already built into a line's range and is also entered as a separate risk event, the model counts it twice. The tail gets fatter and the P80 climbs for no real reason.
Each exposure belongs in one place. If the same risk appears as a line range and as an event, the two entries should represent genuinely different effects, and someone should be able to say what the difference is.
The spread is information too
Teams often fixate on a single P-value and ignore the shape. The distance between P50 and P90 tells you how much the model thinks the outcome could vary. A tight spread on an early, low-definition estimate is itself a finding: either the project really is well defined, or the ranges are too optimistic.
Comparing that spread across estimate versions is one of the more useful things a risk model can do. As design matures, the curve should generally tighten. If it doesn't, the reason is worth understanding.
Questions to ask when someone shows you a P80
Before anyone relies on the number, ask:
- Which estimate version is this run against, and has the estimate changed since?
- What's excluded from the estimate, and therefore from the curve?
- What drives the gap between the base estimate and the P80? Which risks, lines or packages contribute most?
- How is correlation handled? If the answer is "it isn't," expect the spread to be understated.
- Is anything counted twice between line ranges and risk events?
- What's missing? A result that couldn't be calculated should say so, not show up as zero.
If those questions have clear answers, the P80 is a useful, defensible number. If they don't, the slide has a number on it but not much behind it.
Where the software fits
This is the discipline we built Jakten Risk around. Risk runs a Monte Carlo analysis on a specific estimate version and returns P50 through P90 funding levels, cumulative confidence curves, and the contingency at the confidence target your team selects. Package dependencies compile into a correlation matrix, with diagnostics for coverage and validity. Contingency attribution shows how much each risk layer adds at that target, so "why this number?" has an answer on the page.
Results stay tied to the estimate basis they were run against. When inputs change after a run, Risk says the figures changed since the last run rather than presenting old results as current, and a result that isn't available is shown as unavailable, never as zero.
Jakten supports professional judgment. It does not approve or authorize funding decisions. The analysis explains the curve; your leadership decides where to stand on it.
If you'd like to see how that looks on a real workflow, the Jakten Risk page has a short demo and sample reports from a fictional project.